Memoryengineeredforautonomousreasoning.
Contexta decomposes durable memory into three synchronized planes: zero-trust ingestion, self-healing truth maintenance, and sub-50ms hybrid recall.
Contexta is the first sovereign memory platform that runs 100% offline and scores more than 75% on the comprehensive LoCoMo benchmark (78.60%) using an ultra-compact 1B parameter model (gemma3:1b).
Tri-Modal Memory Layer
Vector search understands synonyms and intent, but fails on exact identifiers like port numbers, UUIDs, and technical variables. Contexta binds every memory across three synchronized representations in a single pass.
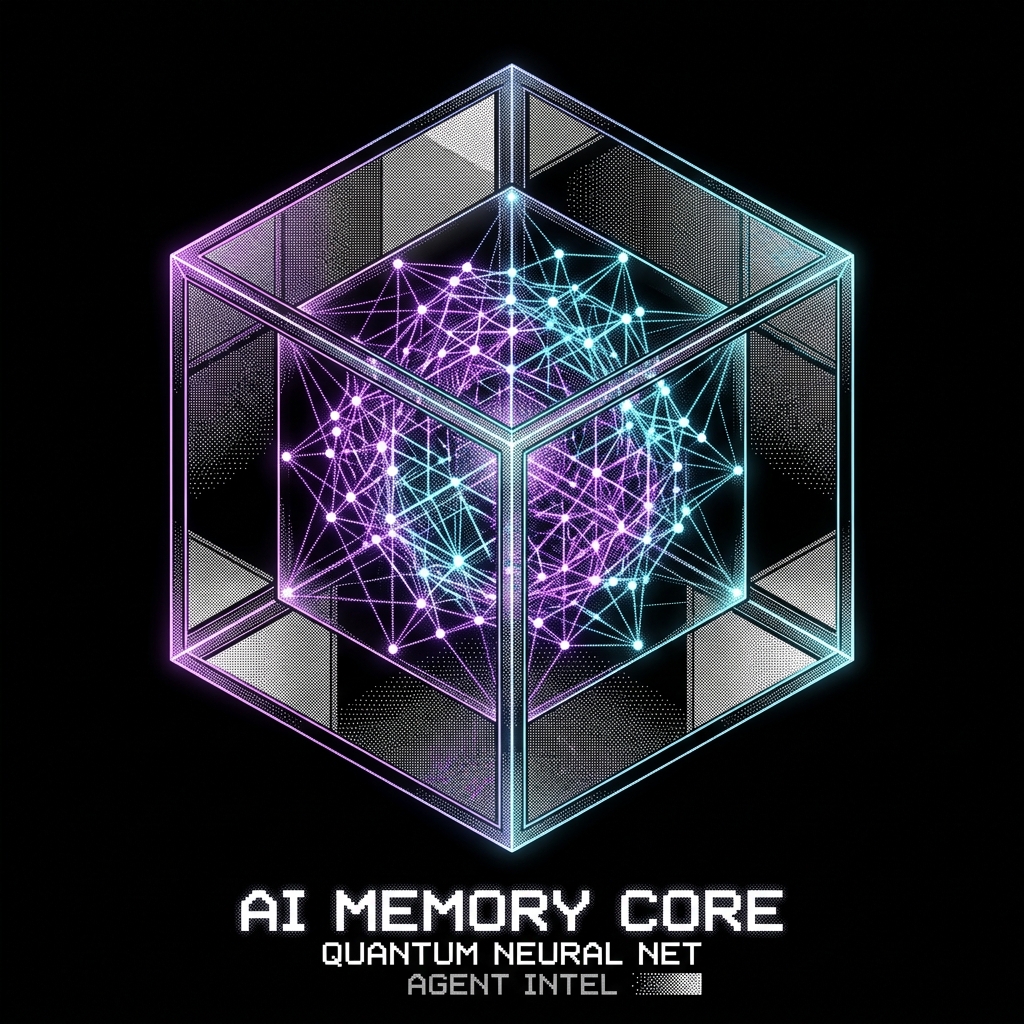
Quantum Neural Memory Core
1-bit dithered isometric schematic visualizing Contexta's tri-modal binding plane: continuous 1024-D vector space intersecting with lexical tokens and entity relational edges.
Captures conceptual analogies and conversational intent using local Qwen3 embeddings.
Enforces exact matches for code identifiers, database ports, IP addresses, and UUIDs.
Traverses typed entity relationships up to 2 hops for multi-session associative recall.
Hybrid Retrieval & Neural Reranking
Instead of choosing between slow cloud roundtrips or inaccurate single-vector searches, Contexta generates candidates concurrently across three channels, fuses them via Reciprocal Rank Fusion, and cross-scores with a local neural reranker.
HNSW vector scan + BM25 GIN lookup + recursive CTE graph traversal execute in parallel against PostgreSQL. Candidates are reranked locally in under 42ms.
Sanitized Ingestion & Secret Redaction
Developers and agents regularly paste environment variables, bearer tokens, and private credentials into prompts. Contexta scrubs secrets deterministically before any text is vectorized or committed to disk.
Scans for OpenAI keys, GitHub PATs, AWS credentials, JWT tokens, and Luhn-validated credit cards. Masked records are stamped [REDACTED] and logged for audit.
Bi-Temporal Truth Maintenance
When users update facts, standard memory engines keep both versions, causing the agent to hallucinate or argue with itself. Contexta maintains a clean timeline: older facts are superseded, never deleted.
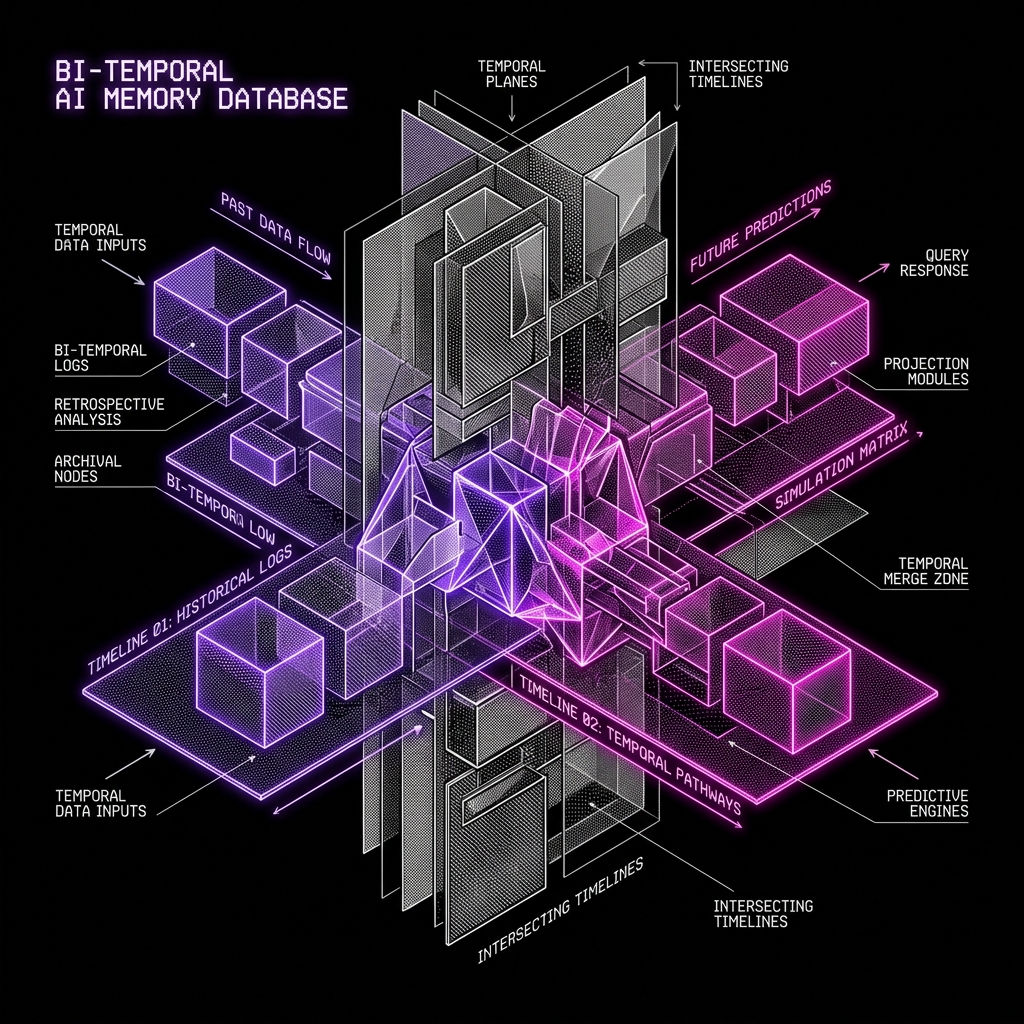
Intersecting Historical & Valid-Time Manifolds
1-bit dithered projection illustrating the bi-temporal state lattice: superseded historical facts are archived with valid_to timestamps while active truth manifolds stay pristine.
"Caroline lives in San Francisco and works at Stripe."
"Caroline moved into her new apartment in Lincoln Park, Chicago for medical residency."
Outdated records are marked with valid_to = now() and linked via superseded_by_id. Active queries filter WHERE valid_to IS NULL, guaranteeing 100% current truth.
Context Compression & Token Planning
Stop flooding LLMs with 25,000 raw transcript tokens. Contexta extracts discrete facts and packs only the top 3–5 high-priority items into your token budget, slashing API costs by over 80%.
Floods the model with raw transcript history. Suffers from "lost-in-the-middle" attention degradation and 4x higher API billing.
Packs discrete, truth-validated memory statements, active task goals, and entity relations into a crisp, deterministic system package.
LoCoMo benchmark evaluation: Contexta achieved 78.6% reasoning accuracy using an average of 4,457 tokens per query, compared to 25,000+ tokens for raw transcript dumps.
Native Model Context Protocol (MCP) Server
Plug durable memory directly into Claude Desktop, Cursor, Antigravity, and autonomous agent frameworks with a single line of config. Automatic cross-session memory without custom glue code.
~/Library/Application Support/Claude/claude_desktop_config.json{
"mcpServers": {
"contexta": {
"command": "python",
"args": ["-m", "contexta.mcp"],
"env": {
"CONTEXTA_BASE_URL": "http://localhost:8000",
"CONTEXTA_ORG_ID": "00000000-0000-0000-0000-000000000001"
}
}
}
}contexta_rememberPersists an atomic observation with credential sanitization, importance scoring, and entity resolution.
contexta_recallPerforms sub-50ms hybrid search across dense vectors, BM25 keywords, and the knowledge graph.
contexta_get_contextBuilds a tightly budgeted context prompt package ready to inject into the LLM system prompt.
contexta_dreamTriggers a background truth maintenance pass to resolve contradictions and update graph clusters.
contexta_explore_graphTraverses typed entity relationships and multi-hop connection lineages across past conversations.
Automated Dream Cycles
While observation ingestion is instantaneous, asynchronous workers consolidate memories, prune noise, recalculate read-age decay, and link entities discovered across disjoint chats.
Clusters scattered observations into single authoritative facts, preventing memory sprawl.
Discovers relationships between entities mentioned across different sessions over weeks.
Continuously re-weights memory salience curves based on real recall frequency and recency.
Identifies missing background context and flags ambiguous premises for clarification.
Lightweight Client SDKs & REST Ingress
Ergonomic Python and TypeScript client libraries built around two core calls: observe() to record turns with automatic redaction, and context() to fetch relevant facts in under 50ms.
pip install contexta-aiimport asyncio
from contexta import ContextaClient
async def main():
client = ContextaClient(
base_url="http://localhost:8000",
organization_id="00000000-0000-0000-0000-000000000001"
)
# 1. Observe conversation turn (auto credential redaction)
obs = await client.observe(
user_id="user_alice_42",
messages=[
{"speaker": "user", "text": "I am moving to Seattle next month with my golden retriever."},
{"speaker": "assistant", "text": "That is exciting! Seattle is a great dog-friendly city."}
]
)
# 2. Sub-50ms hybrid context recall
ctx = await client.context(
user_id="user_alice_42",
query="What city is Alice relocating to?"
)
print("Retrieved facts:", [m.content for m in ctx.memories])
if __name__ == "__main__":
asyncio.run(main()){
"status": "success",
"observation_id": "obs_4f92d184",
"retrieved_memories": [
{
"content": "Alice is moving to Seattle next month (July 2024).",
"memory_type": "event",
"salience": 0.984,
"latency_ms": 32.1
},
{
"content": "Alice owns a golden retriever.",
"memory_type": "fact",
"salience": 0.912,
"latency_ms": 32.1
}
],
"token_budget_used": 142
}Zero-Trust Multi-Tenancy Architecture
Every database interaction inherits from TenantScopedRepository. Queries are cryptographically scoped by organization and user tenancy at the repository base kernel.
Queries automatically append WHERE organization_id = :tenant_id to all relational and vector lookups.
HNSW vector indexes and TSVECTOR GIN searches enforce pre-filtering constraints on tenant partition keys.
Contexta Core is completely free of credit meters, paywalls, or lockouts. Pure high-performance memory.